I am an AI security researcher and engineer. I work on the security and privacy of machine-learning systems: what a model gives away about the data it was trained on, how it can be made to misbehave, and what it takes for a guarantee about either to hold up once the model is deployed. My current focus is the model itself, on how neural networks fail under small, deliberately chosen perturbations of their input and on what it takes to make them fail less: gradient-level attacks and the defences meant to stop them, evaluated the adversarial way rather than the convenient way. I am currently on a research sabbatical devoted to this work, while travelling across Southeast Asia.
Before the sabbatical I spent close to a decade in industry security: product security engineering at Ericsson and Zendesk, then leading security architecture at ZF Group and EY. I hold a joint M.Sc. in Cybersecurity from Grenoble INP – Ensimag and Université Grenoble Alpes, and I am a CISSP. This year I completed Stanford Online's AI Security course and the DeepLearning.AI Machine Learning Specialization, and sat the HTB Certified Offensive AI Expert exam, a seven-day practical AI red-team assessment whose result is due in October.
Most of my time this year goes into building and breaking models: implementing the attacks, putting a control in place, and checking that the control still holds when the attack is run against it properly. What has come out of it so far is on the research and code pages.
What I am working on
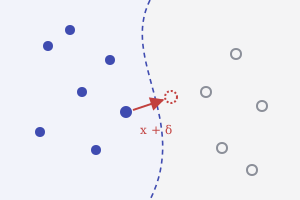
Adversarial robustness at the model and gradient level. A perturbation that no person would notice can move an input across a decision boundary, and the attacks that find such perturbations, from single-step gradient sign methods to iterated projected-gradient and sparse attacks, are the sharpest tools we have for measuring what a model has actually learned. I am working on how these attacks behave against modern classifiers and vision-language models, why so many published defences collapse under an adaptive attacker who knows the defence, and what an evaluation has to include before a robustness claim deserves to be believed.
On the engineering side, I build the harnesses that make such evaluations repeatable: attack implementations checked against reference results, robustness curves rather than single accuracy numbers, and controls that show the measurement can tell a robust model from a brittle one before it is used to judge either.
Contact
Email is the best way to reach me: contact@calisternnona.com for anything, or research@calisternnona.com for questions about the research. I read everything and reply to most of it.